Technology
Nine core technologies, one GPU-centric data service
GPUFlow combines an end-to-end direct data path, hardware offload, and AI-driven storage intelligence to serve the AI factory's repeated train → infer cycle.
01 · Data path
GPUDirect zero-copy I/O
GPUs pull storage data directly over RDMA, through both POSIX and object (S3) interfaces, with cuFile/cuObject-compatible drivers.
CPU-mediated copies → direct GPU path
02 · Availability
Sub-30-second failover
Distributed mirroring and an automated DR controller keep training running through component or site failures.
Long service outages → RTO ≤ 30 s
03 · Intelligence
AI-powered storage resources
eBPF-based telemetry and access-pattern models predict load and faults, then re-place data and resources ahead of demand.
Static placement → predictive optimization
04 · Cloud native
Unified VM + container storage
One storage stack serves virtual machines and Kubernetes pods on the same nodes, with CSI-driven dynamic provisioning and non-disruptive rebalancing.
Single-runtime storage → heterogeneous runtimes
05 · Offload
DPU-accelerated data processing
NVMe-oF/RDMA, encryption, compression, and checksums are offloaded to a domestic FPGA-based DPU, with UEC-ready congestion control.
CPU-bound protocol stacks → DPU offload
06 · Observability
Workload-aware diagnosis
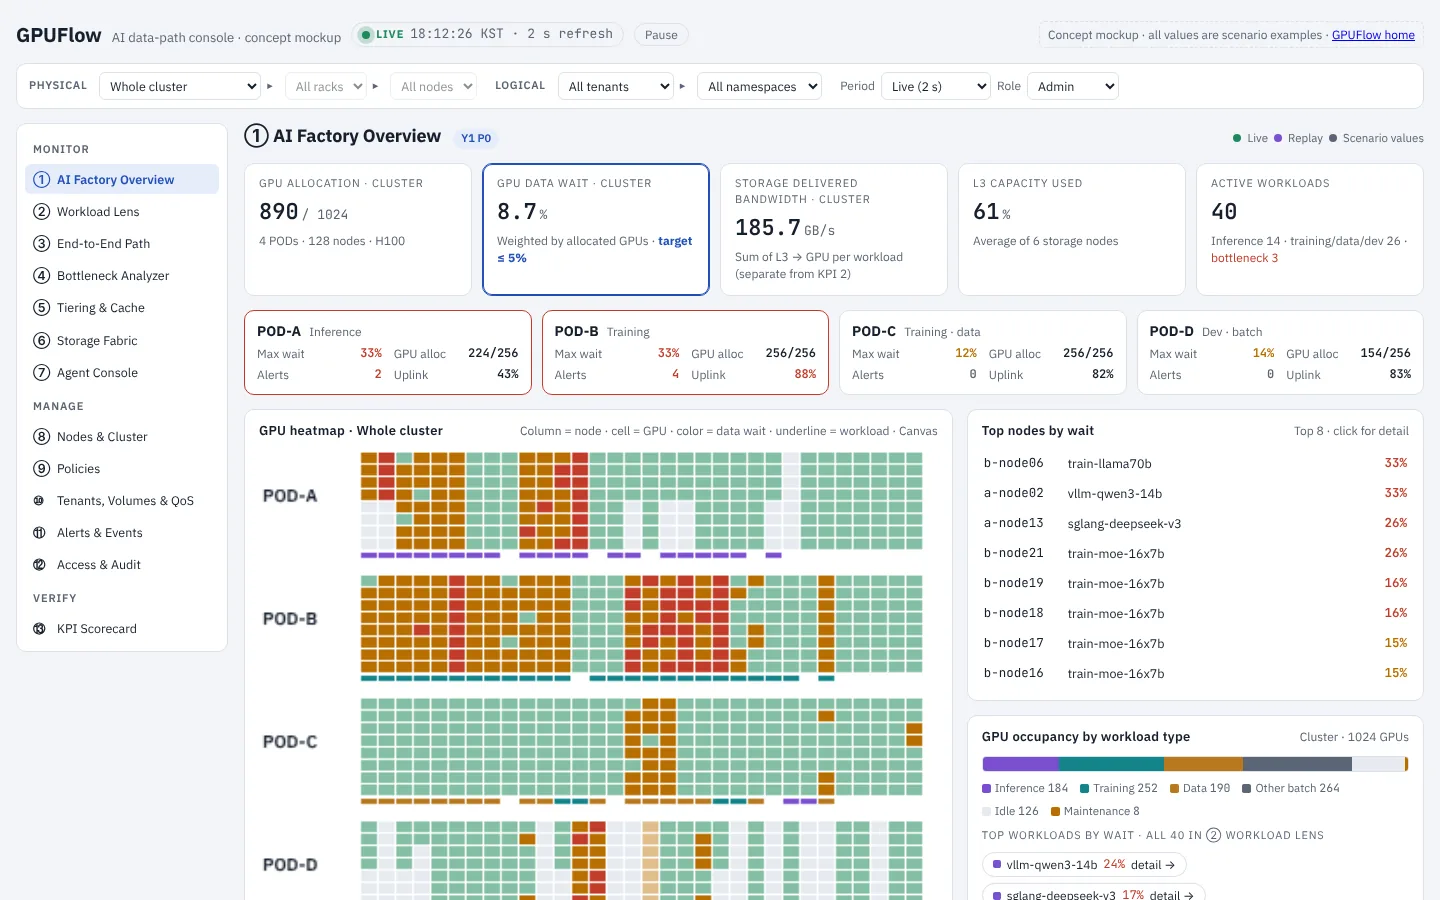
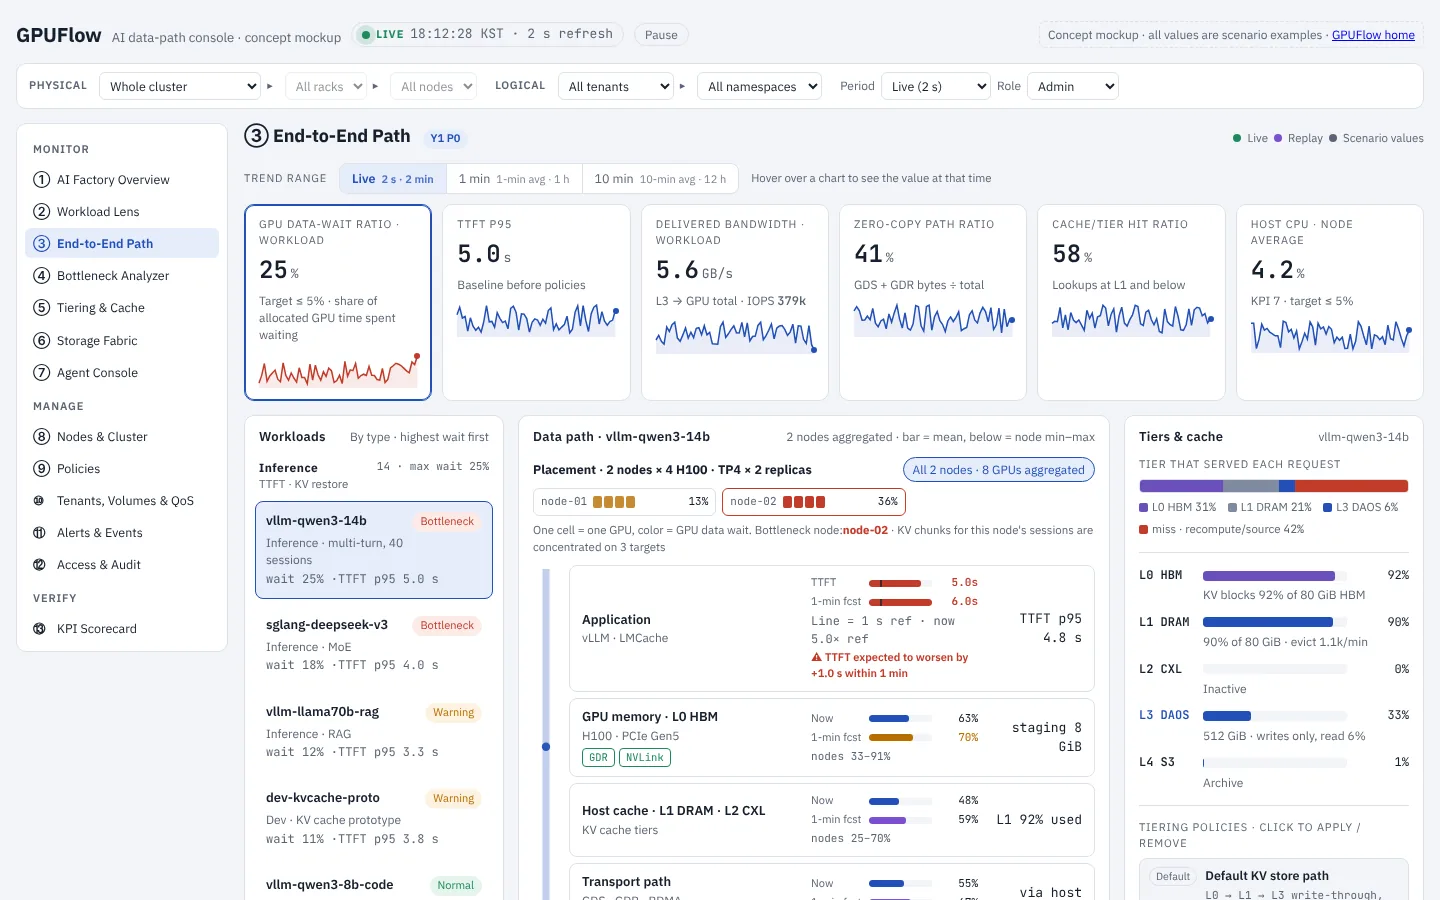
Correlates GPU idle time with storage and network latency to explain why GPUs starve, from cluster view down to a single volume.
Infrastructure-only monitoring → bottleneck root cause
07 · Validation
Internationally certified performance
Performance is proven through IO500 and MLCommons MLPerf Storage, together with a new benchmark for AI inference storage.
In-house benchmarks → global certification
08 · Memory
CXL metadata acceleration
A CXL memory tier with ghost caching, batched metadata handling, and contention-aware asynchronous I/O scheduling.
Metadata stalls → microsecond-scale access
09 · Inference
KV-cache & framework integration
PyDAOS bindings pass PyTorch/CuPy tensors to storage without conversion, a vLLM connector, and an adaptive GPUDirect/host-staging path selector.
Format conversion → native tensor I/O
GPUFlow‑COREZero-copy, accelerator-attached parallel storage engine
GPUFlow‑ACCELCXL/DPU I/O acceleration & compute offload module
GPUFlow‑ManagerWorkload-aware tiering & unified management platform
GPUFlow‑HCIHyper-converged compute, network & storage with a CXL memory pool
GPUFlow‑SYSIntegrated HW + SW appliance for AI factories